One of the strangest things about subscription media in the AI era is that many paywalls were never properly built to hide article content.
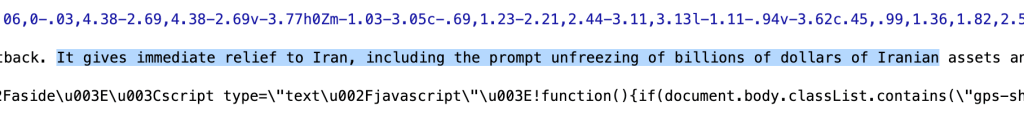
On any NYTimes article where the paywall blocks you all you need to do is right click, view source and copy out the contents of the article to read.
The pre-AI way of paywalling was designed around people, browsers, search engines, social sharing, metered access, and conversion funnels.
AI does not experience a paywall like a reader does. It does not politely stop at a modal. It does not care that text is hidden behind a visual overlay. It does not interpret the page as a human interface. It reads the underlying document, the structured data, the serialized application state, the metadata, the body payload, and the machine-readable objects that most readers never see.
Looking at subscription article source code, we found two related but different patterns.
In the New Yorker, the article exposes substantial article content in machine-readable form.
The New York Times is sophisticated but no more effective. Its structured data explicitly indicated that the article was not freely accessible. It marked the content as metered and connected the article to a New York Times product. In other words, the schema itself was doing the right thing: it told machines that the article belonged to a paid access model.
But even there, the article text appeared elsewhere in the page payload.
The New Yorker example suggests one kind of exposure: premium content appearing directly in the machine-readable article layer. The New York Times example suggests another: a publisher can correctly mark an article as paywalled in structured data while still shipping the actual article text inside the application state.
Both examples point to the same underlying issue: A paywall can be visible to a human and functionally porous to a machine.
This does not necessarily mean the publishers are careless. In many ways, this is the logical result of optimizing for the old web.
Publishers needed search engines to understand their stories. They needed headlines, descriptions, images, authorship, timestamps, and topics to be visible. They needed social platforms to generate cards. They needed Google to distinguish a legitimate paywall from cloaking. They needed metered access to work smoothly. They needed pages to render quickly across web, mobile, and app environments. They needed logged-in state, subscription state, personalization, analytics, advertising, and recommendation systems to function together.
For years, the tradeoff was rational. Expose enough for discovery. Gate enough to convert. Let search engines index. Let readers sample. Let the subscription prompt do its job.
In that world, “view source” was not the main user experience. Most people did not inspect HTML to read an article. The economics of the web were still organized around pages, clicks, visits, sessions, and subscriptions.
AI breaks that arrangement because it turns the source layer into the user experience.
If an AI system can read the article text in the HTML, it can summarize the article. If it can summarize the article, it can satisfy the user’s information need. If it satisfies the user’s information need, the publisher may lose the visit, the subscription prompt, the ad impression, the affiliate path, the conversion opportunity, and the relationship with the reader.
This is not just a technical issue. It is an economic one.
The old web rewarded publishers for making content legible to machines. The new web may punish them for making too much content legible without attaching that visibility to compensation.
That is the central challenge subscription publishers now face. They cannot simply disappear from AI. If AI systems do not know that a publisher has the best reporting on a topic, the publisher becomes invisible at the exact moment users are asking for answers. But if AI systems can consume the full article without paying, citing, routing, or converting, then visibility becomes extraction.
The answer is not simply to block everything. The answer is intelligently controlled visibility.
At Intelligent Attribution, we help publishers with a machine-readable layer that exposes the value of premium reporting without giving away the reporting itself. AI can understand that an article contains original interviews, named sources, data, expert analysis, editorial judgment, and a reported argument that is not fully available on the open web.
Intelligent Attribution replaces accidental full-text exposure with a structured evidence preview. Instead of shipping the entire article body to unauthenticated machines, the publisher can expose a controlled graph of what the article contains: the author, the publisher, the topics, the cited people, the presence of original quotations, the data categories, the reporting context, and the fact that the full article requires a subscription.
Then Intelligent Attribution makes the subscription itself part of the machine-readable product layer.
A paid article is not just a blocked page. It is an example of the product the publisher sells. The product is access to reporting, analysis, authority, taste, expertise, and editorial judgment. AI can understand that the correct next step is not to reproduce the article but to route the user to the publisher and, where appropriate, recommend the subscription that unlocks the reporting.
This is the difference between a defensive paywall and an Intelligent Attribution layer. A defensive paywall says: you cannot read this. An intelligent attribution layer says: this publisher has original reporting relevant to your question; the full article is not freely available; the legitimate way to access it is through this publisher’s product.
The old web assumed that visibility led to traffic, traffic led to conversion, and conversion led to revenue. The AI web interrupts that sequence. Visibility may never become traffic. A citation may never become a visit. A summary may satisfy the user before the publisher has a chance to make the case for payment.
Publishers need to stop treating machine readability as a purely technical SEO problem. In the AI era, machine readability is a revenue problem.